
SQL Server PIVOT: turning sensor readings into one row per instant
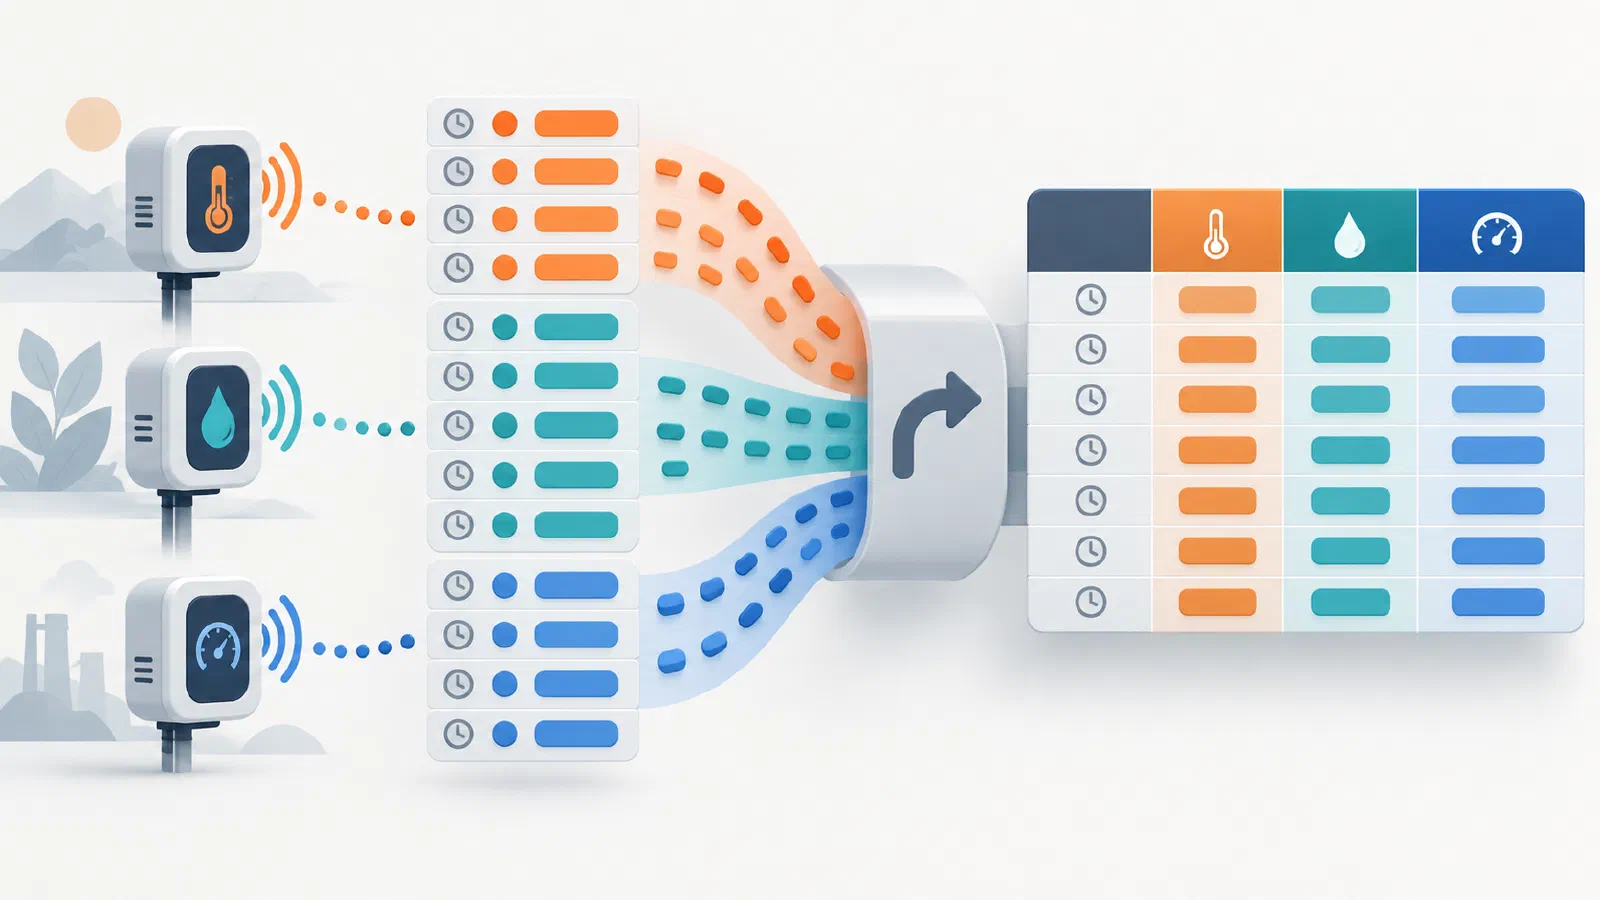
Imagine receiving sensor readings every five minutes. Each message contains a time, a sensor ID, a metric name, and a value. Storing messages as they arrive is convenient: if a new metric appears tomorrow, it simply adds more rows. But a report consuming the data wants something else: one row per time and sensor, with temperature, humidity, and pressure in separate columns.
Turning those rows into columns is pivoting the data. It comes up often in data engineering and time series work: long format is convenient for ingesting events, while wide format suits certain reports, exports, models, and consumers that expect a fixed set of variables per observation.
From readings to a sample table
In long format, each row is a reading. We will use observed_at for the timestamp, sensor_id for the device, metric for the measurement type, and metric_value for the value. In this example, we interpret the times as UTC and the values as degrees Celsius, percent humidity, and hectopascals, depending on the metric. The DATETIME2 type does not itself record a time zone.
You can reproduce the example in SQL Server with these twelve rows:
CREATE TABLE sensor_readings (
    observed_at  DATETIME2(0) NOT NULL,
    sensor_id    VARCHAR(16) NOT NULL,
    metric       VARCHAR(20) NOT NULL,
    metric_value DECIMAL(8,2) NOT NULL
);

INSERT INTO sensor_readings
    (observed_at, sensor_id, metric, metric_value)
VALUES
    ('2026-09-25T10:00:00', 'S-01', 'temperature', 20.00),
    ('2026-09-25T10:00:00', 'S-01', 'temperature', 22.00),
    ('2026-09-25T10:00:00', 'S-01', 'humidity',    45.00),
    ('2026-09-25T10:00:00', 'S-01', 'pressure',  1012.00),
    ('2026-09-25T10:00:00', 'S-02', 'temperature', 19.00),
    ('2026-09-25T10:00:00', 'S-02', 'humidity',    50.00),
    ('2026-09-25T10:00:00', 'S-02', 'pressure',  1011.00),
    ('2026-09-25T10:05:00', 'S-01', 'temperature', 21.50),
    ('2026-09-25T10:05:00', 'S-01', 'humidity',    44.00),
    ('2026-09-25T10:05:00', 'S-01', 'pressure',  1012.50),
    ('2026-09-25T10:05:00', 'S-02', 'temperature', 19.50),
    ('2026-09-25T10:05:00', 'S-02', 'pressure',  1011.50);
The table does not enforce a unique key across time, sensor, and metric: we want to keep two temperatures for S-01 at 10:00 and explicitly decide what to do with them. A production system would also need to distinguish a second measurement from a retransmitted message.
First, inspect the data as stored:
SELECT observed_at, sensor_id, metric, metric_value
FROM sensor_readings
ORDER BY observed_at, sensor_id, metric, metric_value;
You will find two temperature rows for S-01 at 10:00 and no humidity row for S-02 at 10:05. A missing reading is not the same thing as a humidity reading of zero.
The result we want
Before writing the query, we need to fix its grain: each output row will represent one observed_at and sensor_id pair. We want this result (values shown to two decimal places):
| observed_at | sensor_id | temperature | humidity | pressure |
|---|---|---|---|---|
| 2026-09-25 10:00:00 | S-01 | 21.00 | 45.00 | 1012.00 |
| 2026-09-25 10:00:00 | S-02 | 19.00 | 50.00 | 1011.00 |
| 2026-09-25 10:05:00 | S-01 | 21.50 | 44.00 | 1012.50 |
| 2026-09-25 10:05:00 | S-02 | 19.50 | NULL | 1011.50 |
The 21.00 is the average of 20.00 and 22.00. The NULL means that no humidity reading exists for that time and sensor. The database may display more decimal places for an AVG result; the table above is formatted for readability.
Solving it with PIVOT in SQL Server
SQL Server provides the PIVOT operator to turn values from one column into result columns while aggregating the corresponding readings:
SELECT
    observed_at,
    sensor_id,
    [temperature],
    [humidity],
    [pressure]
FROM (
    SELECT observed_at, sensor_id, metric, metric_value
    FROM sensor_readings
) AS readings
PIVOT (
    AVG(metric_value)
    FOR metric IN ([temperature], [humidity], [pressure])
) AS wide_readings
ORDER BY observed_at, sensor_id;
Read it from the inside out:
- The
readingssubquery supplies only the two dimensions, the metric, and its value. FOR metricsays that values ofmetricwill become column headings.IN (...)lists the columns to create. Square brackets delimit identifiers in T-SQL; the list is not discovered automatically.AVG(metric_value)decides what to put in a cell when multiple readings exist for the same metric, time, and sensor.wide_readingsis the required alias for the resulting table;ORDER BYdisplays the rows in time order.
The subquery also protects the grain. SQL Server groups by input columns other than the pivot column and the aggregated value. Passing an event ID or ingestion time through as well could produce multiple rows for the same time and sensor. Dropping sensor_id, on the other hand, would mix readings from both devices.
Aggregation is not just a syntax requirement: the engine needs a rule to reduce several rows to one cell. We chose the average to make this visible, but the correct rule depends on what the readings mean. If the two temperatures were retransmissions of the same event, we should deduplicate first; if we wanted the latest reading, we would need another timestamp or identifier and a rule for choosing it. AVG is not automatically right in either case.
The same transformation with CASE and GROUP BY
We can express the same idea through conditional aggregation, without PIVOT:
SELECT
    observed_at,
    sensor_id,
    AVG(CASE WHEN metric = 'temperature' THEN metric_value END) AS temperature,
    AVG(CASE WHEN metric = 'humidity'    THEN metric_value END) AS humidity,
    AVG(CASE WHEN metric = 'pressure'    THEN metric_value END) AS pressure
FROM sensor_readings
GROUP BY observed_at, sensor_id
ORDER BY observed_at, sensor_id;
GROUP BY creates one row per time and sensor. Each CASE passes through values for one metric and returns NULL for the others; AVG ignores those NULLs. For S-01 at 10:00 it averages the two temperatures. For S-02 at 10:05 it finds no humidity value and returns NULL. This version is useful when we want to see each column’s logic explicitly or write more portable SQL.
What about MySQL?
MySQL does not provide SQL Server’s PIVOT operator. We can create the same table by changing the temporal type and reuse the previous INSERT; the date format with a T is valid in MySQL too:
CREATE TABLE sensor_readings (
    observed_at  DATETIME NOT NULL,
    sensor_id    VARCHAR(16) NOT NULL,
    metric       VARCHAR(20) NOT NULL,
    metric_value DECIMAL(8,2) NOT NULL
);
The query is the conditional aggregation we just used:
SELECT
    observed_at,
    sensor_id,
    AVG(CASE WHEN metric = 'temperature' THEN metric_value END) AS temperature,
    AVG(CASE WHEN metric = 'humidity'    THEN metric_value END) AS humidity,
    AVG(CASE WHEN metric = 'pressure'    THEN metric_value END) AS pressure
FROM sensor_readings
GROUP BY observed_at, sensor_id
ORDER BY observed_at, sensor_id;
In MySQL, CASE WHEN without ELSE returns NULL when the condition is false, and AVG ignores null values. It therefore produces the same logical result. Date syntax and column types differ between engines, but the idea of grouping the dimensions and calculating each metric separately is the same.
When the metrics change
This is a static pivot: we wrote temperature, humidity, and pressure into the query. If battery_level arrives, it will not appear as a column until we change the SQL. The CASE solution has the same constraint: a new output column needs a new expression.
When the metrics are not known in advance, we can build the column list and query using dynamic SQL: a dynamic pivot. In SQL Server that means handling identifiers and input values carefully. It deserves its own article. A result schema that changes from one run to the next can also complicate downstream consumers; sometimes keeping long format is the better choice.
UNPIVOT is a related operator that turns columns back into rows. It cannot fully undo this example: the 21.00 average no longer contains the separate 20.00 and 22.00 readings, and null values can disappear when unpivoting.
In the database or outside it?
A pipeline may receive telemetry in long format, store it that way, and deliver a wide view to a report or a particular consumer. If the data is already in SQL Server or MySQL, doing the transformation in the database can avoid extracting many rows, transferring them, reshaping them in Python, and writing them back. Knowing SQL well lets us make that choice instead of automatically reaching for a script.
That does not mean SQL will always be faster. Data volume, indexes, the query plan, available memory, pipeline architecture, and transformation complexity all matter. Another tool may fit better for a hard-to-express business rule or for data already being processed outside the database. The important first step is to decide what one row represents and how repeated readings should be resolved; the choice of operator comes after that.